Structured data influences AI citation the way a name tag influences a meeting: it tells the engine exactly who and what each page is about, which removes the ambiguity that makes a model credit your claim to somebody else. It does not manufacture authority, and Google says AI Overviews need no special markup at all. The types worth implementing are few, and most of the ROI sits in getting five of them exactly right
This is the implementation guide we apply to our own sites and client sites, including the details that decide whether the markup helps or just sits there
Which schema types actually matter for AI search?
Six types cover everything that matters; everything else is decoration:
| Type | Where | What it tells the engine |
|---|---|---|
| Organization | Sitewide (layout) | Your legal name, address, licence, contact — the entity anchor every other type references |
| BlogPosting | Every article | Headline, dates, author, publisher — plus mainEntityOfPage so the article is identifiable as a citable object |
| Person | Author bylines + author page | The author is a real entity with name, jobTitle, url, image — the E-E-A-T surface |
| FAQPage | Pages with real Q&A | Question/answer pairs made machine-readable — eligible for extraction into direct answers |
| BreadcrumbList | Every non-home page | Site structure and the page's position in it |
| Service | Service/hub pages | What you sell, who provides it, where |
The one thing they all share: every type should reference the same Organization @id. Our setup uses a single @id anchor (https://phiilabs.com/#organization) that BlogPosting publisher, Service provider, and ProfilePage worksFor all point to — that is how an engine resolves ten markup blocks into one entity instead of ten.
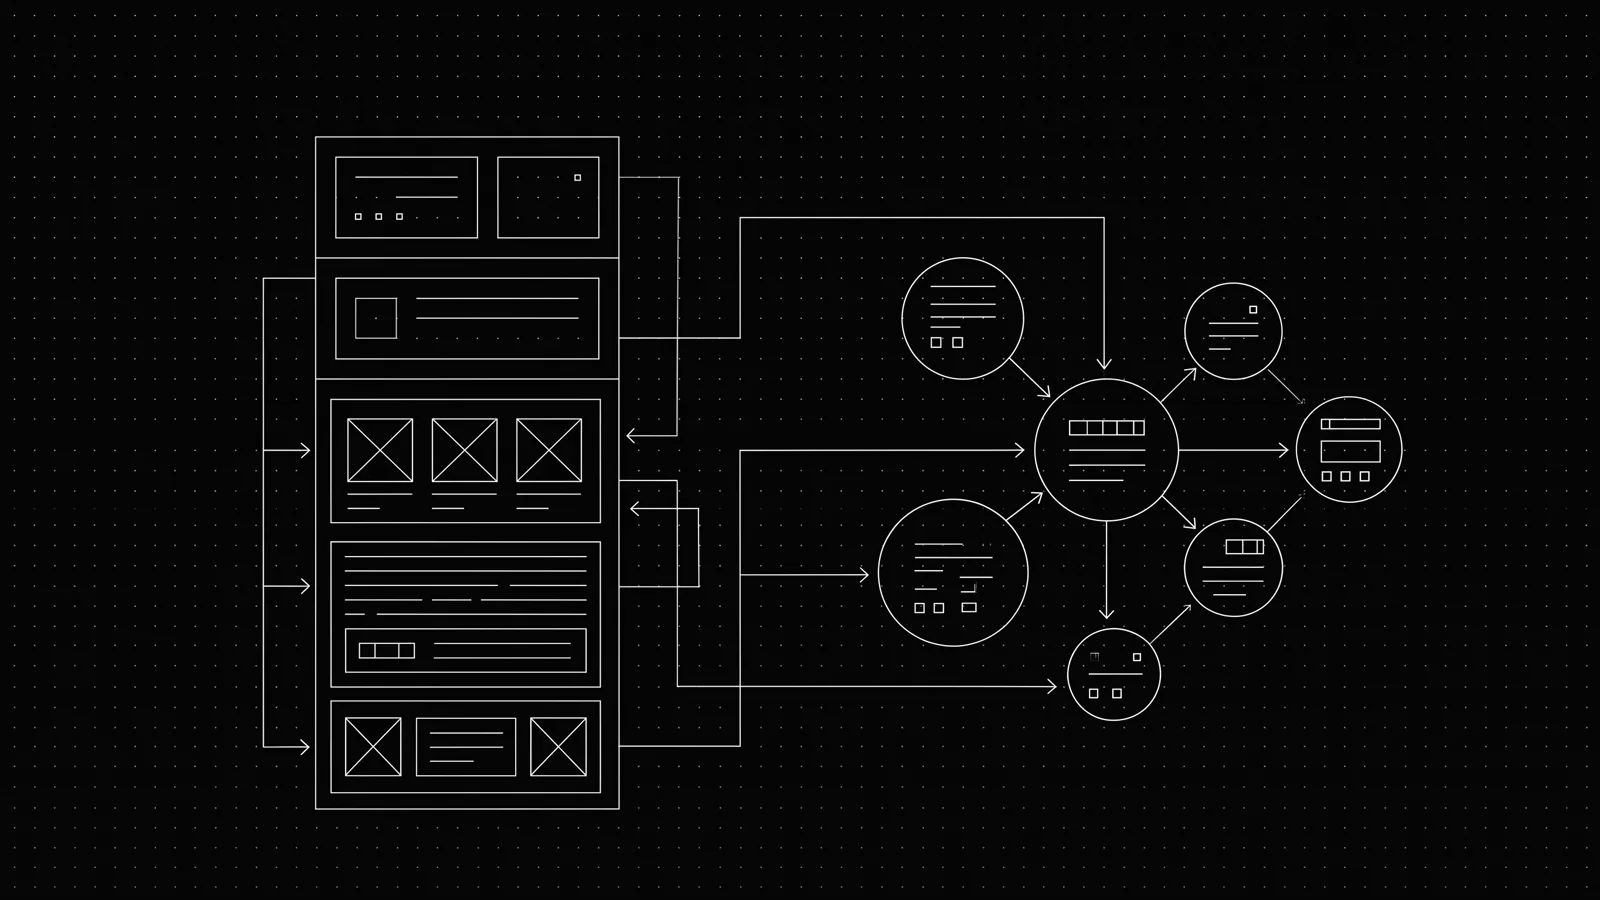
Without that shared @id, each type reads as a separate entity to the engine
Client after client, the fix that changed the visibility was giving every markup block one shared organization id. Ten blocks pointing at the same entity read as one company; without it, the engine sees ten different strangers.
What does a correct BlogPosting block look like?
The canonical pattern we ship on this site, in JSON-LD inside a <script type="application/ld+json"> tag (the Next.js emission pattern is JSON.stringify(data).replace(/</g, "\\u003c")):
{
  "@context": "https://schema.org",
  "@type": "BlogPosting",
  "headline": "…",
  "datePublished": "2026-10-05",
  "dateModified": "2026-10-05",
  "mainEntityOfPage": { "@type": "WebPage", "@id": "<canonical>" },
  "image": "<absolute cover URL>",
  "author": {
    "@type": "Person",
    "@id": "https://phiilabs.com/author/sergei-suvorin#person",
    "name": "Sergei Suvorin",
    "jobTitle": "Co-founder, PHII Labs",
    "url": "https://phiilabs.com/author/sergei-suvorin",
    "image": "https://phiilabs.com/img/author-sergei-suvorin.webp"
  },
  "publisher": { "@type": "Organization", "@id": "https://phiilabs.com/#organization" }
}
The author Person deserves special attention: the @id on the article's author and the author-page ProfilePage mainEntity must be the same string. That is what lets an engine merge the two nodes into one person. Without it, your author is ten different "Sergei Suvorin" strings instead of one entity
Which schema types are wasted effort?
Review stars without attestable reviews, AggregateRating you made up, Article instead of BlogPosting (semantic loss), and SpeakableSpecification for a site nobody will voice-search. The bigger trap is marking up content that does not exist on the page — Google calls this out explicitly in its structured-data guidelines, and engines learn to distrust markup that claims more than the visible text
llms.txt belongs in the same honest category: Google has not confirmed using it, so it is not a citation lever. It is cheap to publish and serves as a canonical-facts index for crawlers that do read it, which is why this site has one — but a page's prose is still what gets cited
What matters more than the markup?
The passage itself. Engines cite self-contained, sourced, specific passages: a paragraph that answers a question plainly, carries a number or a named source, and agrees with other passages the engine already trusts. The GEO-bench study (arXiv:2311.09735) found that adding statistics, quotations and citations lifted visibility 30–40% on the benchmark — none of those three edits are markup. Schema clarifies entities; passages earn the citation. The full mechanics sit in how to get cited by ChatGPT and Perplexity and the layer-by-layer split in SEO vs AEO vs GEO.
If you want us to check whether your markup and your prose actually line up, our AI search visibility service runs a fixed prompt-set audit and reports exactly which of your pages get cited
What are the implementation mistakes that break it?
Three we fix most often. First, escaped < characters: in a Next.js app the JSON-LD script is emitted with JSON.stringify(data).replace(/</g, "\\u003c") so the HTML serializer does not mangle it — skip that and the block parses in some readers and breaks in others. Second, string duplication instead of @id references: writing the full Organization object inline in every BlogPosting means the engine sees ten copies of you, not one entity. Third, markup that overstates the visible page — a FAQPage whose questions are not on the page is a markup violation, not a signal
The validation loop is boring and mandatory: Google Rich Results test for render-level validity, the Schema.org validator for semantics, and the extracted JSON-LD in the built HTML (not the source) to confirm what crawlers actually get
Where does this fit in the bigger picture?
Schema is the bottom of the visibility stack: it answers "who is this page about" unambiguously so the engine does not have to guess. On top of it sit the answer-first passages, the FAQ markup those passages earn, and the citations themselves. The measurement side (how to prove any of it worked) is in how to get cited by ChatGPT and the audit methodology is in SEO vs AEO vs GEO
What about the markup Google does not document?
Two patterns the industry guesses at rather than confirms. sameAs links to LinkedIn, Crunchbase or a UAE business directory help entity resolution across the web — engines use them to merge your Organization node with profiles they already trust, though neither vendor publishes a guaranteed effect. knowsAbout on a Person (topics the author demonstrably covers) is speculative but harmless — it costs a line of markup and communicates the author's domain to any engine that reads it. We ship both on our own author entity because they are cheap, plausible signals; what we do not do is call them ranking factors, because nobody has proven they are
The takeaway
Ship six types — Organization, BlogPosting, Person, FAQPage, BreadcrumbList, Service — dedupe everything through one Organization @id, give your author a real Person node with a URL and image, and spend the remaining effort on the passages themselves. Markup clarifies; content earns
FAQ
What structured data should I use for AI search?
Organization on every page, BlogPosting with author on articles, FAQPage where genuine Q&A exists, BreadcrumbList for site structure, and Service on commercial pages. These disambiguate entities; they do not manufacture authority
Does FAQ schema help with answer engine optimization?
It makes Q&A pairs machine-readable and eligible for rich results, which helps extraction. It is one signal among many — the passage quality and source authority matter more than the markup
Does Google use llms.txt?
No confirmed adoption. It costs an afternoon to publish and serves as a canonical-facts index for crawlers that do read it, but it is not a ranking or citation lever by itself
Can schema alone get my brand cited?
No. Google states AI Overviews need no special markup. Schema clarifies who you are; citation comes from content worth quoting — specific, sourced, self-contained passages
Sources
- arXiv:2311.09735arxiv.org